
简体中文 | English
Project page: https://cosmicrealm.github.io/style-talking/
GitHub README shows clickable preview images instead of inline video players because GitHub does not reliably render external MP4 embeds. For direct playback, please view the project page.
Style-Talking is a zero-shot audio-driven digital human system for cloning speaking style from a reference video. It builds speaking-style prompts from reference expression coefficients, enabling style transfer across identities from source video and target audio.
Given a source video and a target audio clip, Style-Talking predicts LivePortrait expression motion from wav2vec audio features. The default path remains compatible with the original LivePortrait decoder, while the recommended public gallery uses an optional RefGAN renderer checkpoint for sharper reference-aware mouth details. In both paths, a final face blending step preserves the original non-face regions.
source video + target audio
-> wav2vec features
-> style-prompted lip motion generation
-> LivePortrait expression patching
-> original LivePortrait decoder or optional RefGAN renderer
-> final face blend
-> playable MP4
The reference source video keeps its original speech track for style-prompt extraction. The target driving audios used in the results are synthesized with Qwen3-TTS.
The main gallery below uses the optional renderer_refgan.pt renderer. Original decoder outputs are kept in the comparison section.
Chinese |
English |
Japanese |
Korean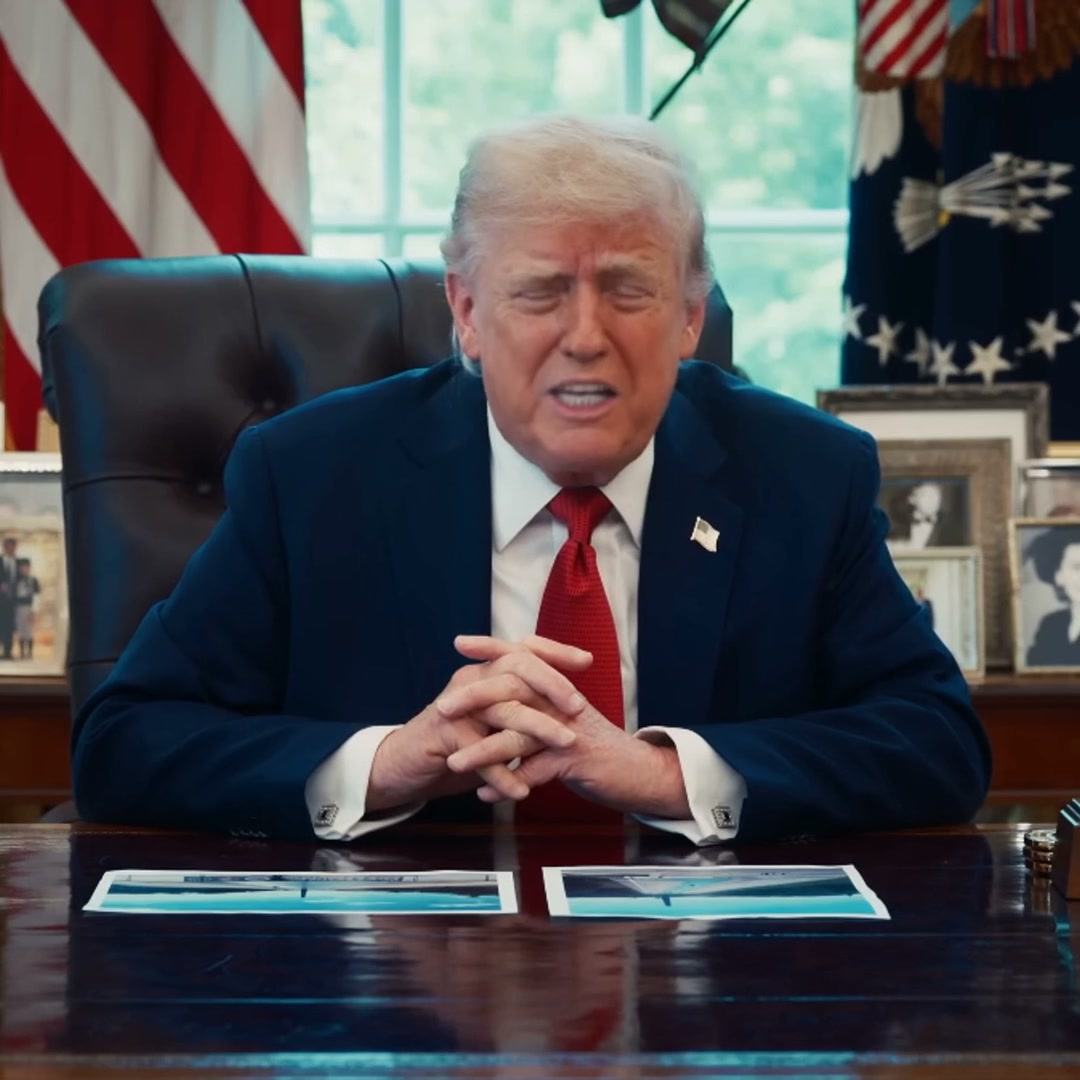 |
| Source Video | Style-Talking | Style-Talking-RefGAN |
|---|---|---|
Michelle Yeoh / English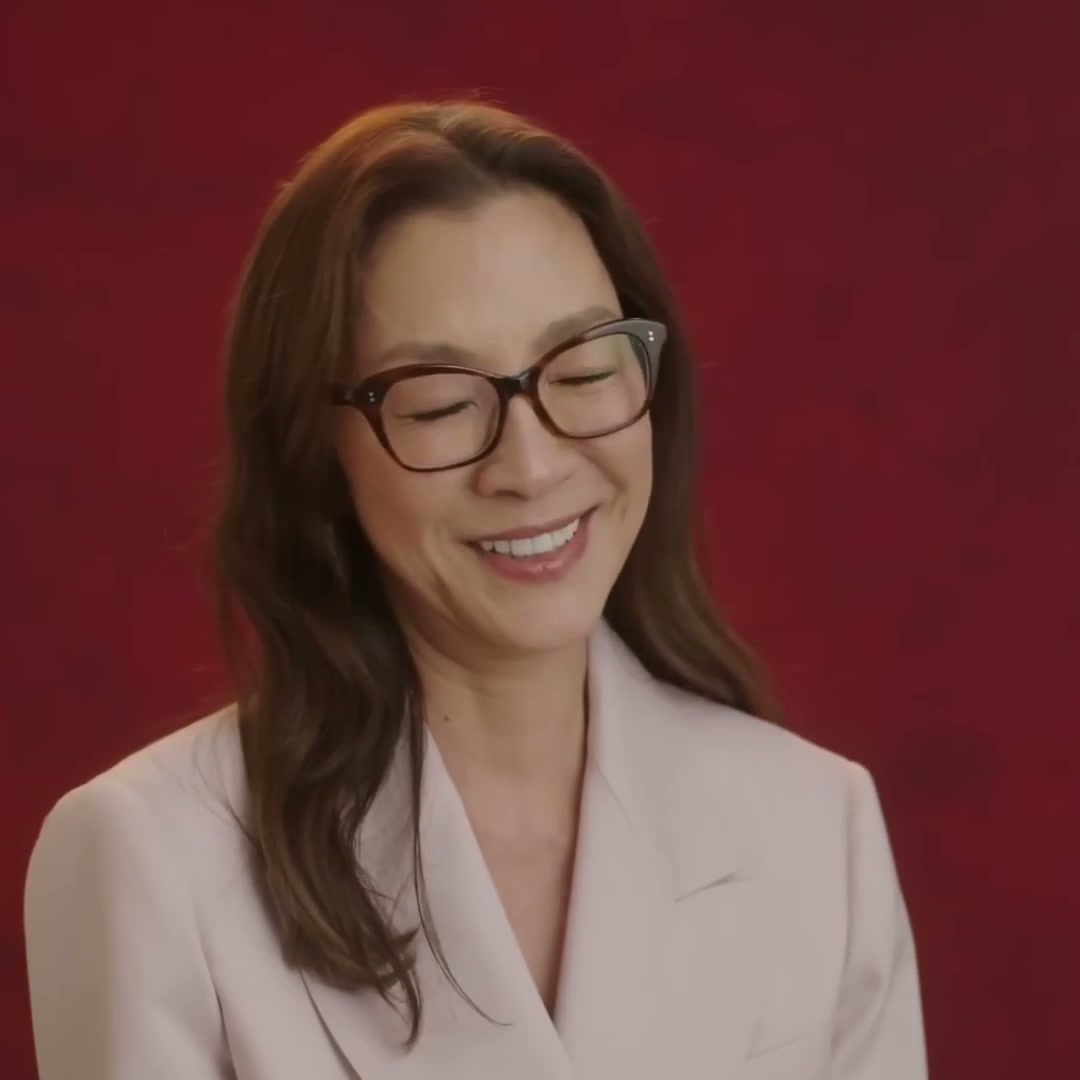 |
Original decoder |
RefGAN renderer |
Zendaya / English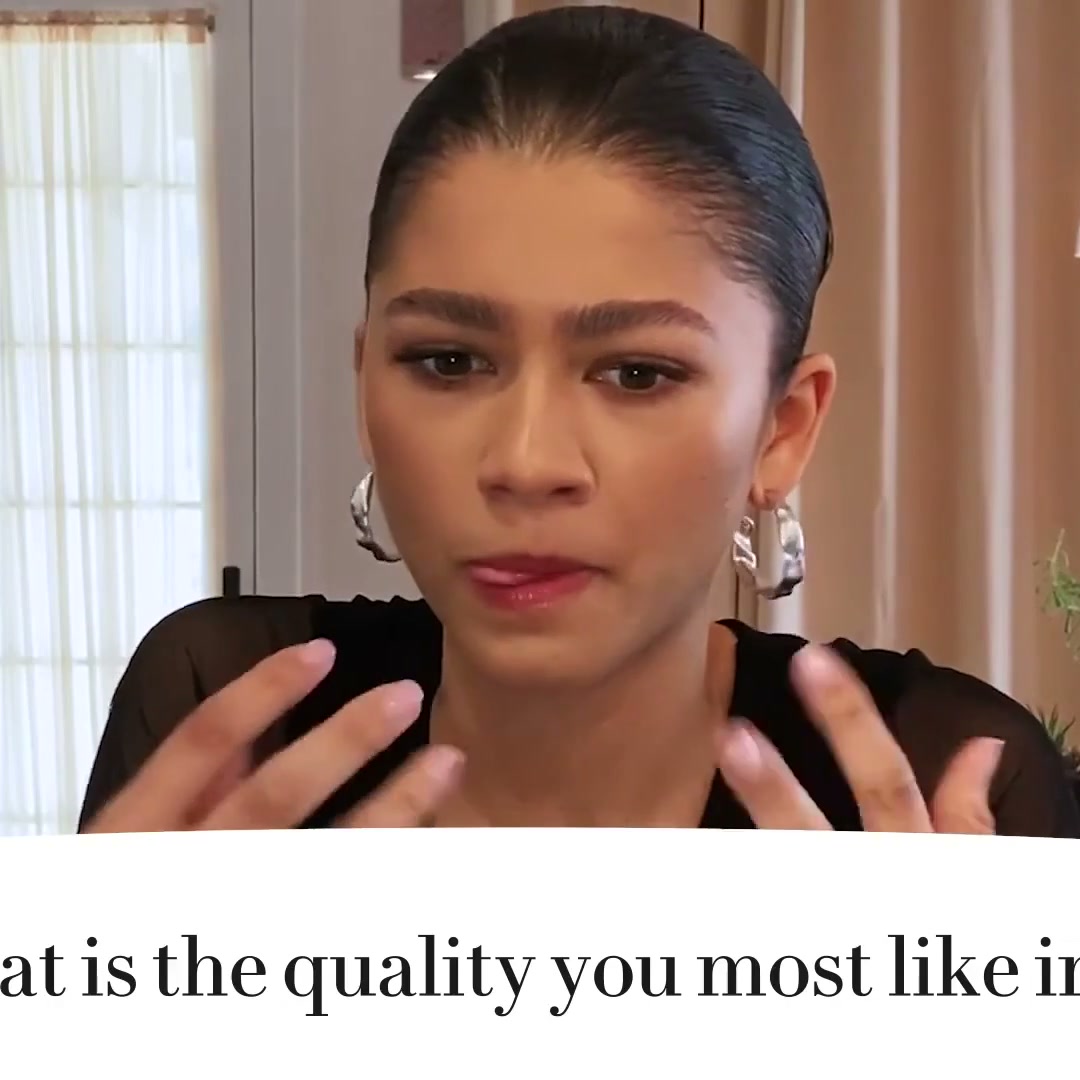 |
Original decoder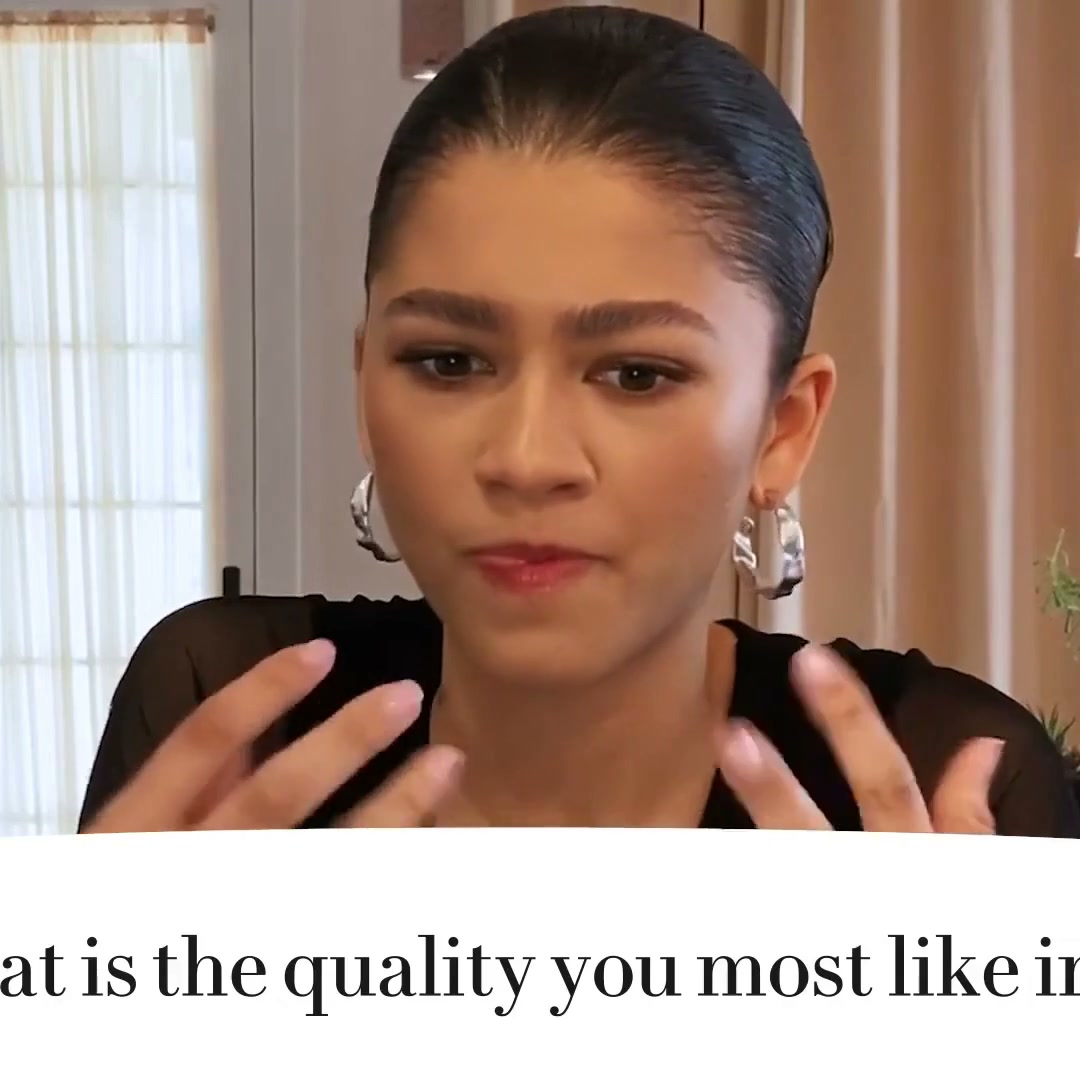 |
RefGAN renderer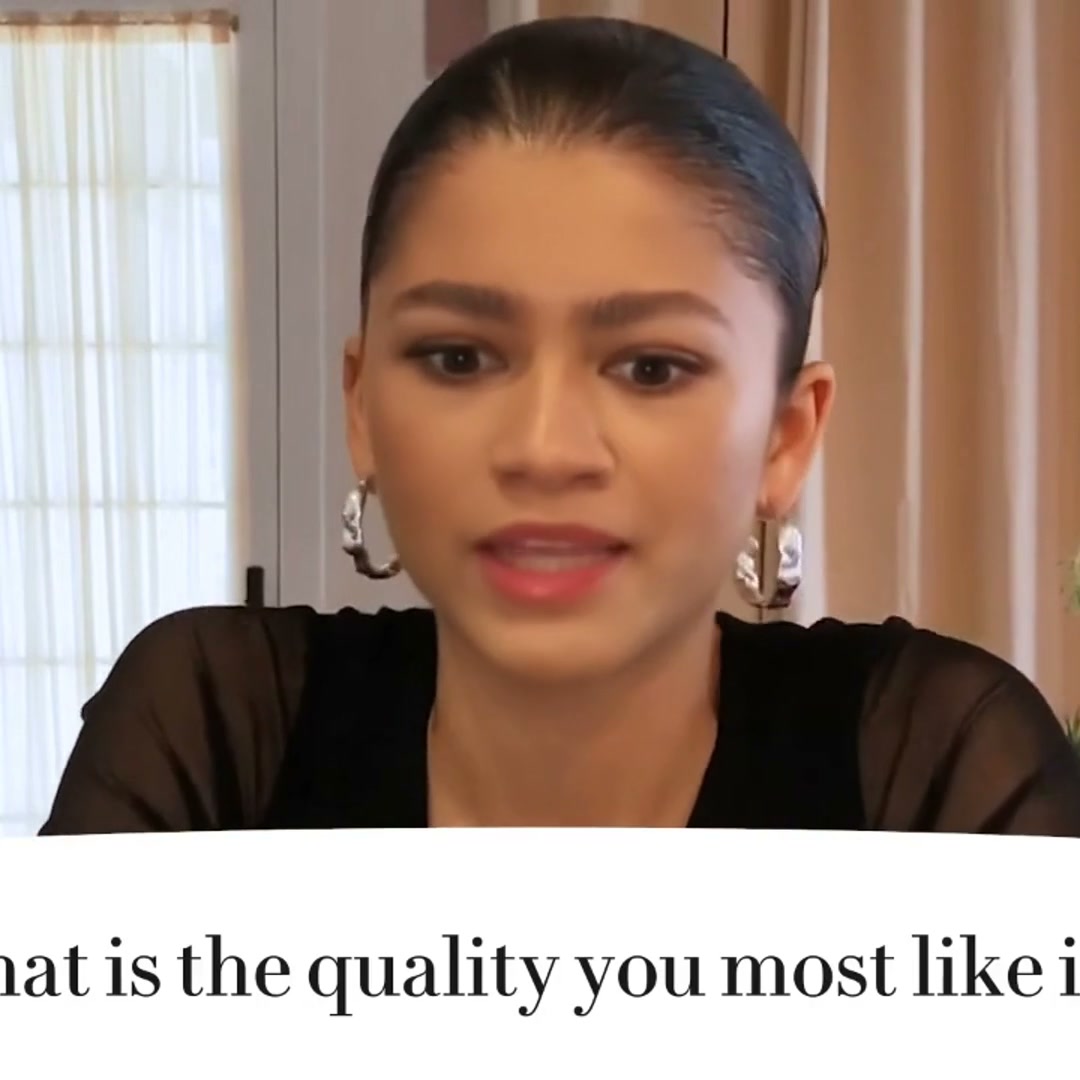 |
Liu Yifei / Chinese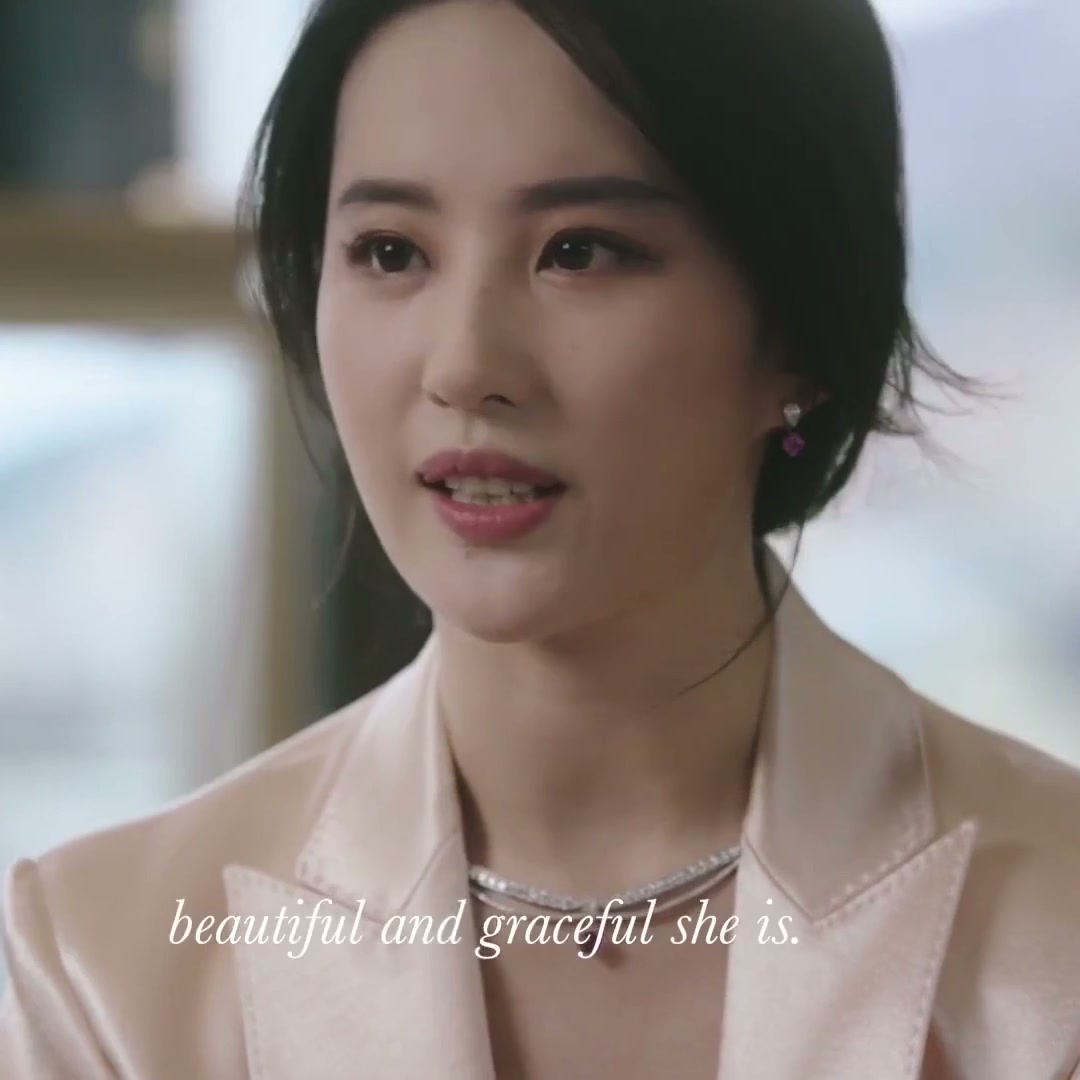 |
Original decoder |
RefGAN renderer |
Morgan Freeman / English |
Original decoder |
RefGAN renderer |
Jake Gyllenhaal / Japanese |
Original decoder |
RefGAN renderer |
Timothee Chalamet / Korean |
Original decoder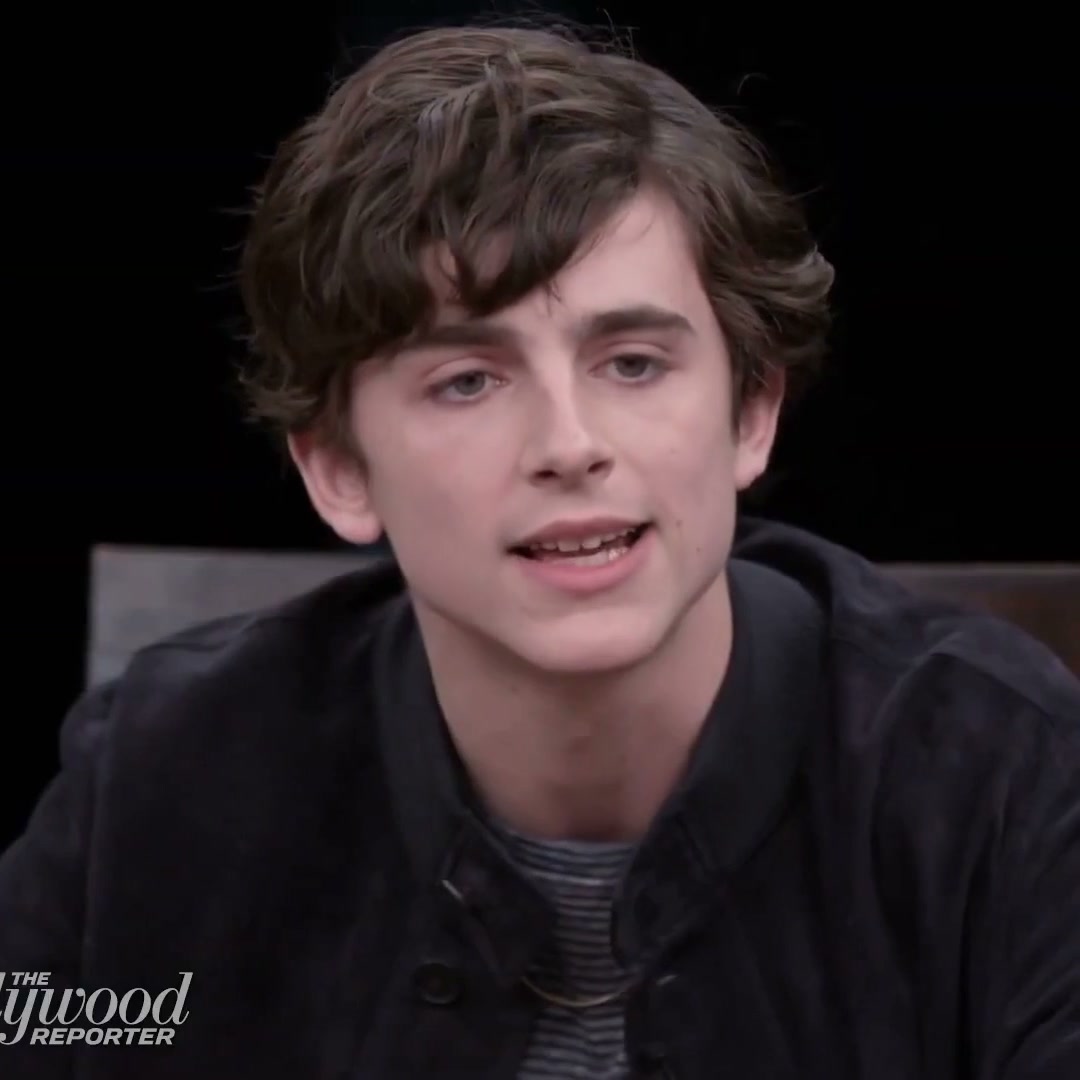 |
RefGAN renderer |
The same Audio2Motion output and source/target audio are used in both columns; only the renderer changes.
| Original LivePortrait decoder | RefGAN renderer |
|---|---|
Trump / Chinese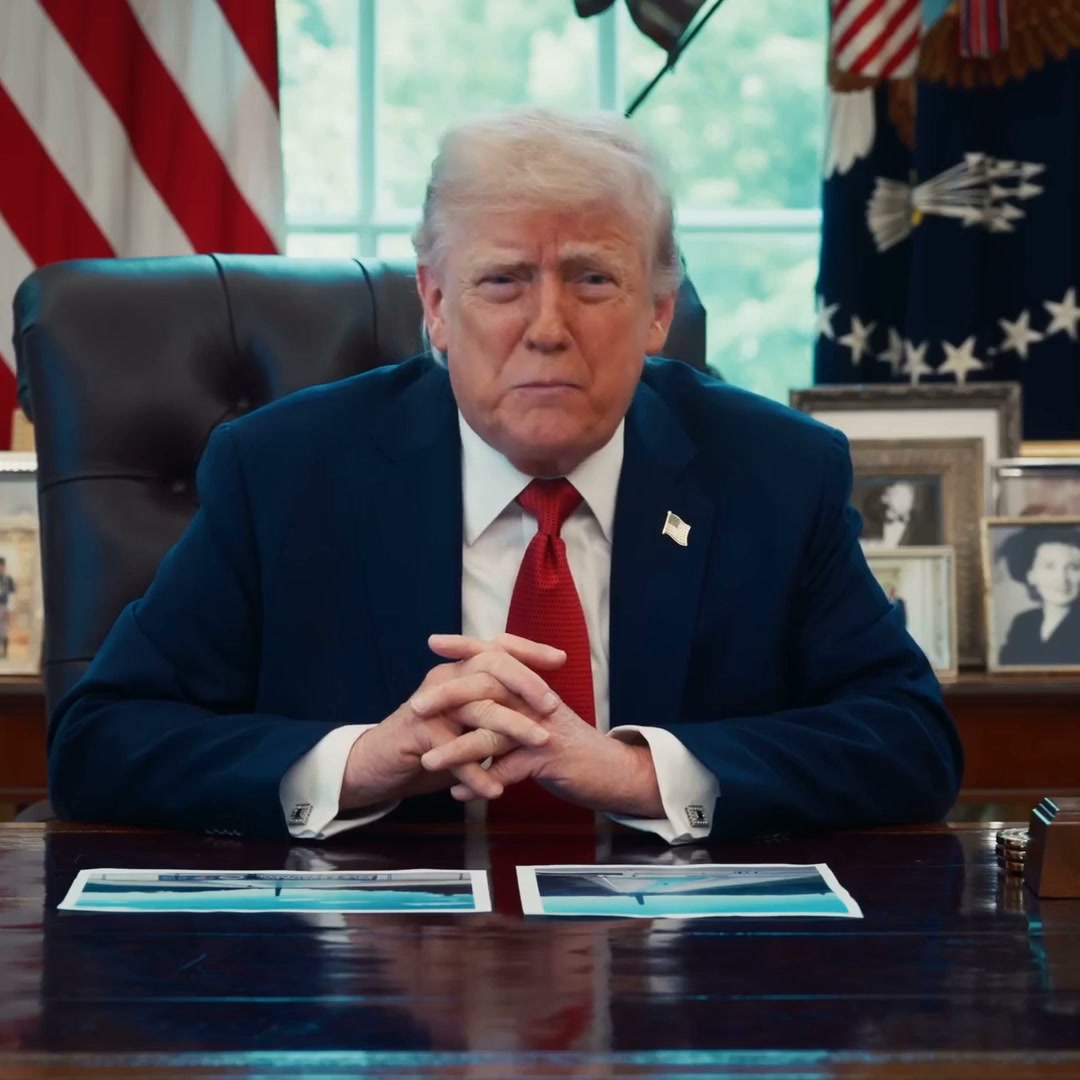 |
Trump / Chinese |
Trump / English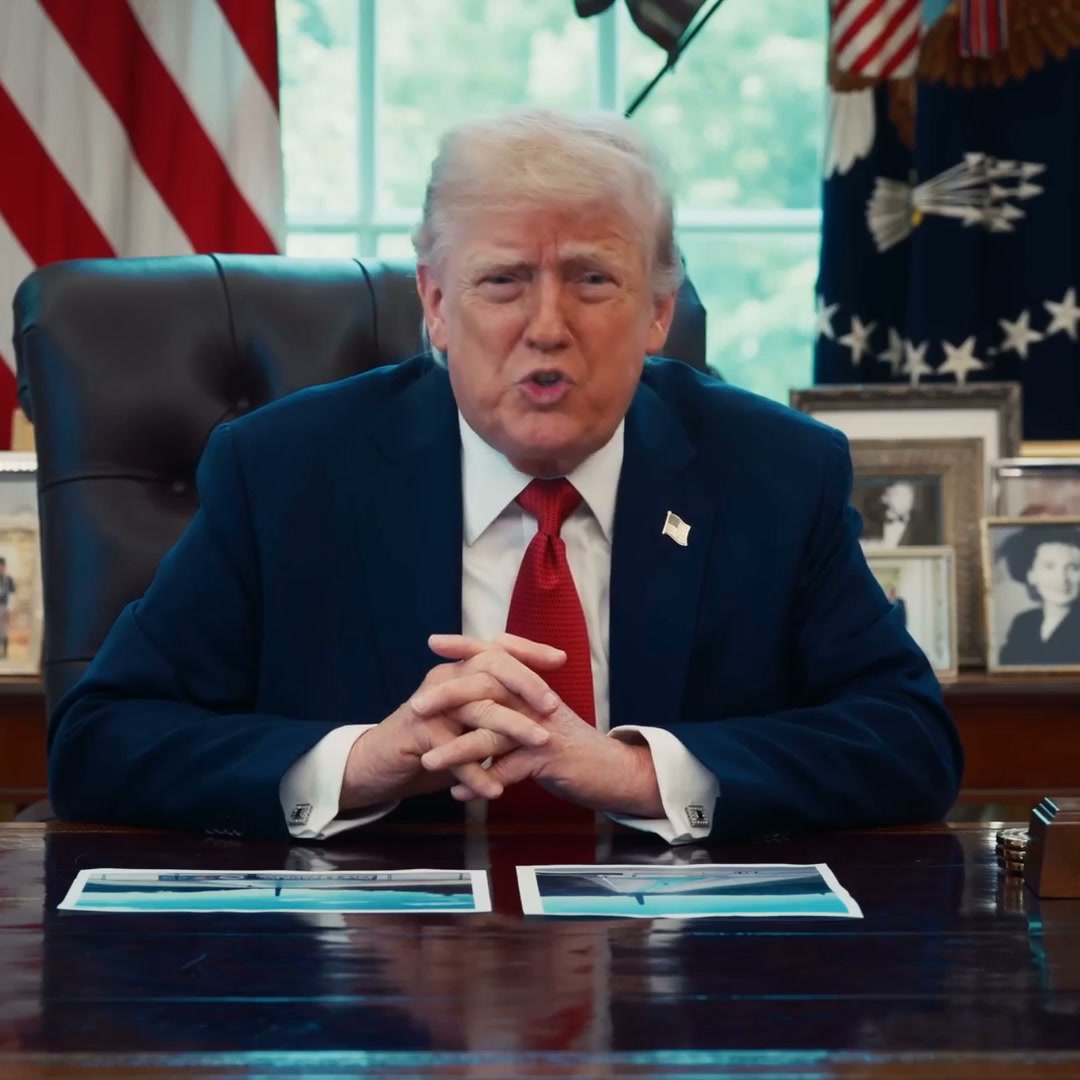 |
Trump / English |
Trump / Japanese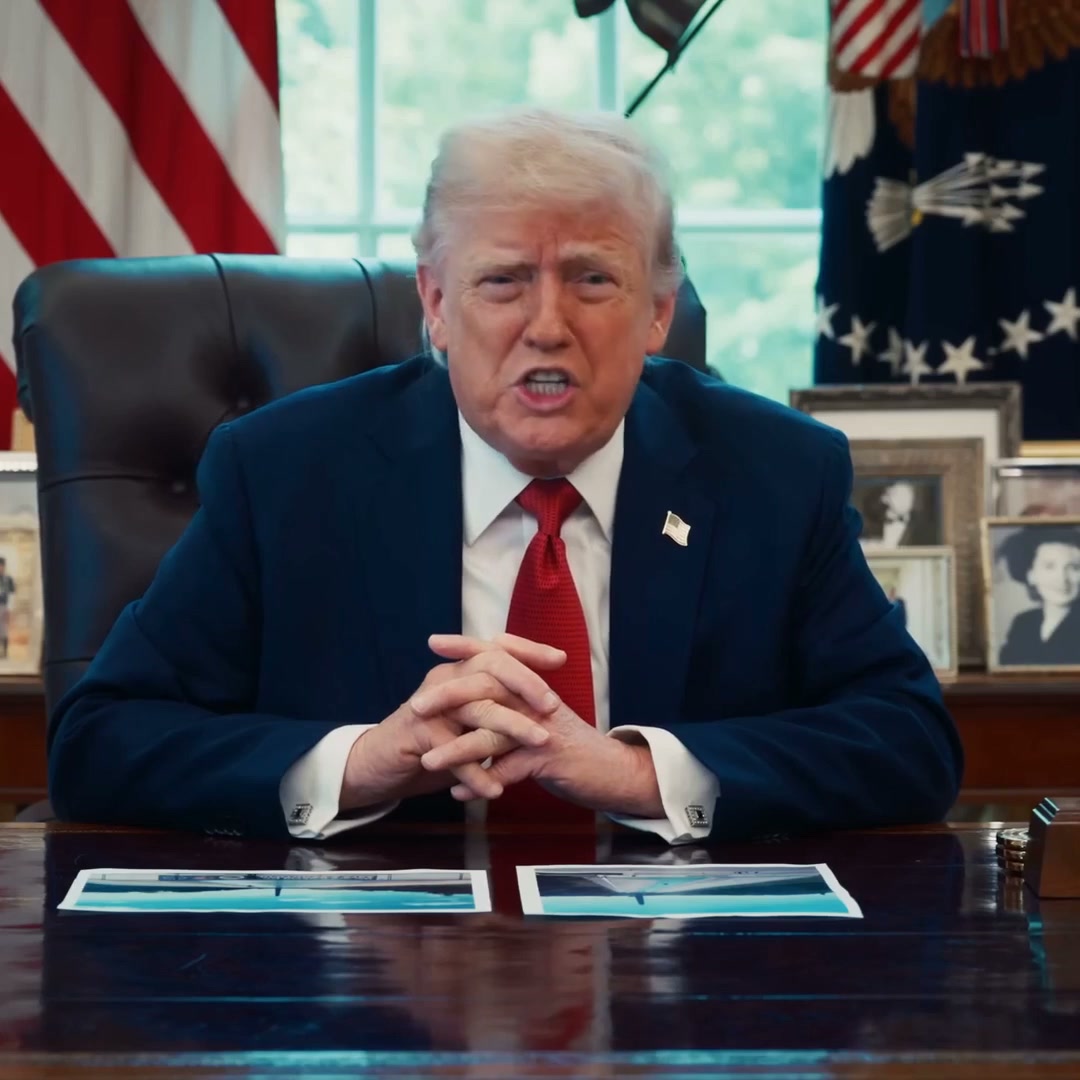 |
Trump / Japanese |
Trump / Korean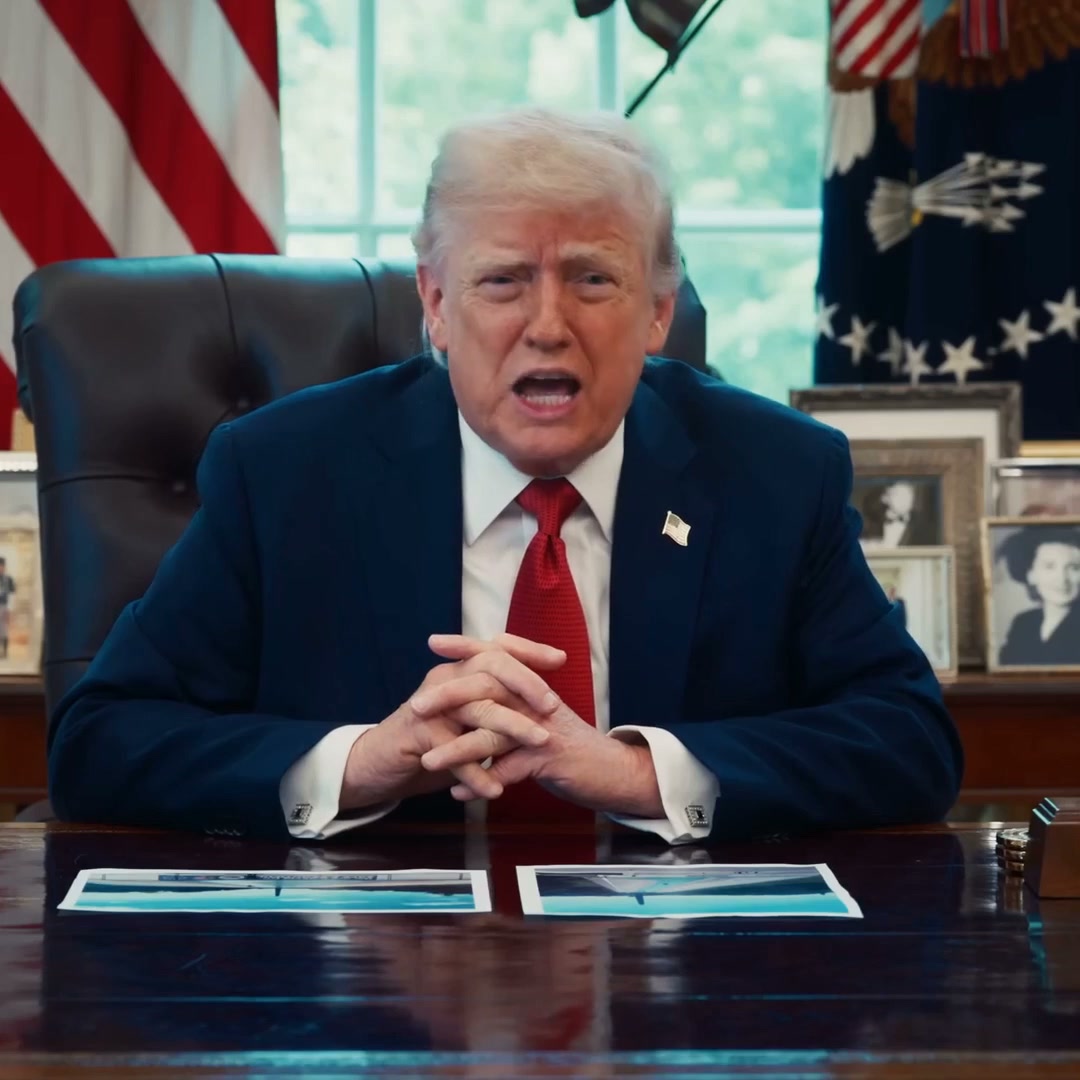 |
Trump / Korean |
| Michelle Yeoh / English |
Michelle Yeoh / English |
| Zendaya / English |
Zendaya / English |
| Liu Yifei / Chinese |
Liu Yifei / Chinese |
| Morgan Freeman / English |
Morgan Freeman / English |
| Jake Gyllenhaal / Japanese |
Jake Gyllenhaal / Japanese |
| Timothee Chalamet / Korean |
Timothee Chalamet / Korean |
| Style-Talking RefGAN |
Wav2Lip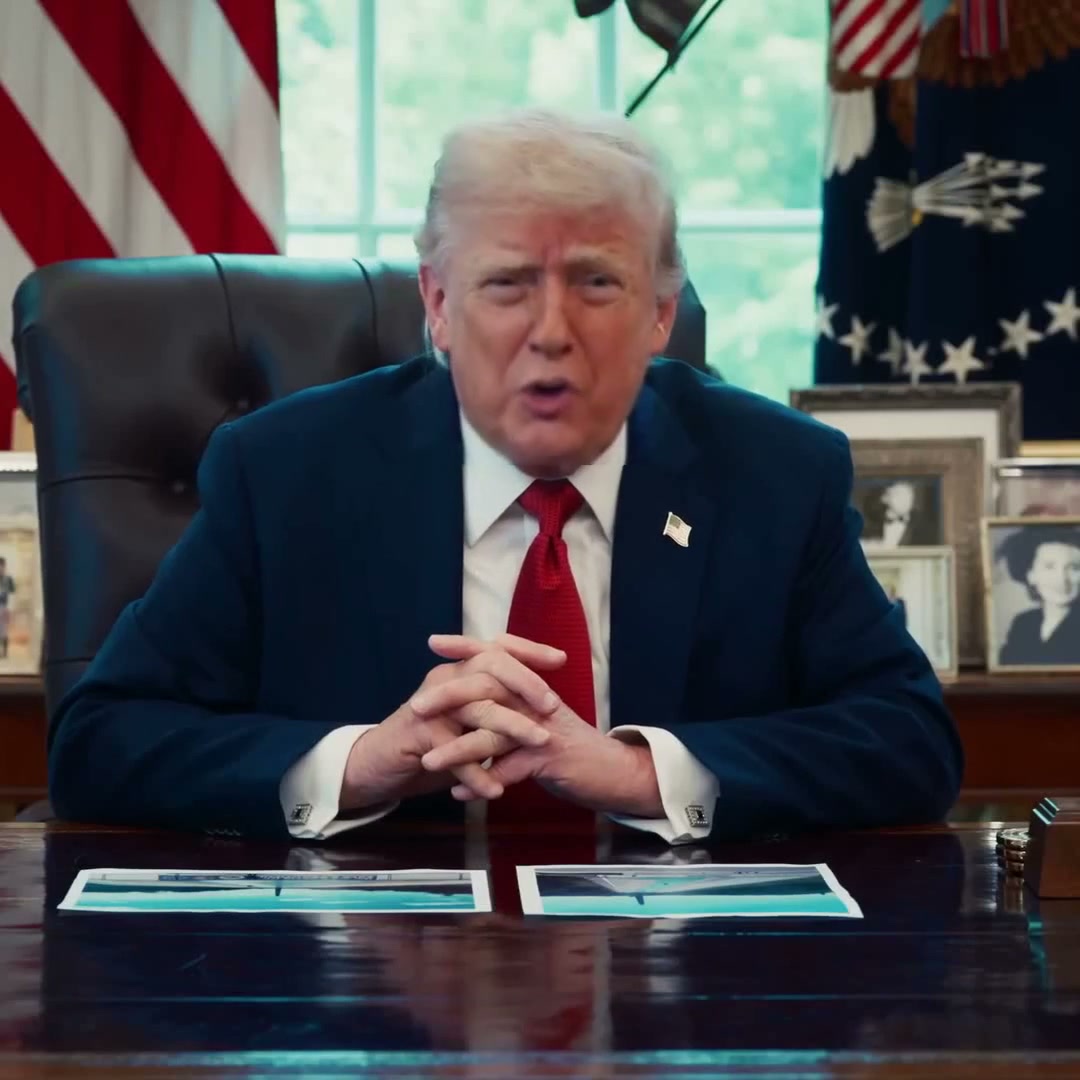 |
MuseTalk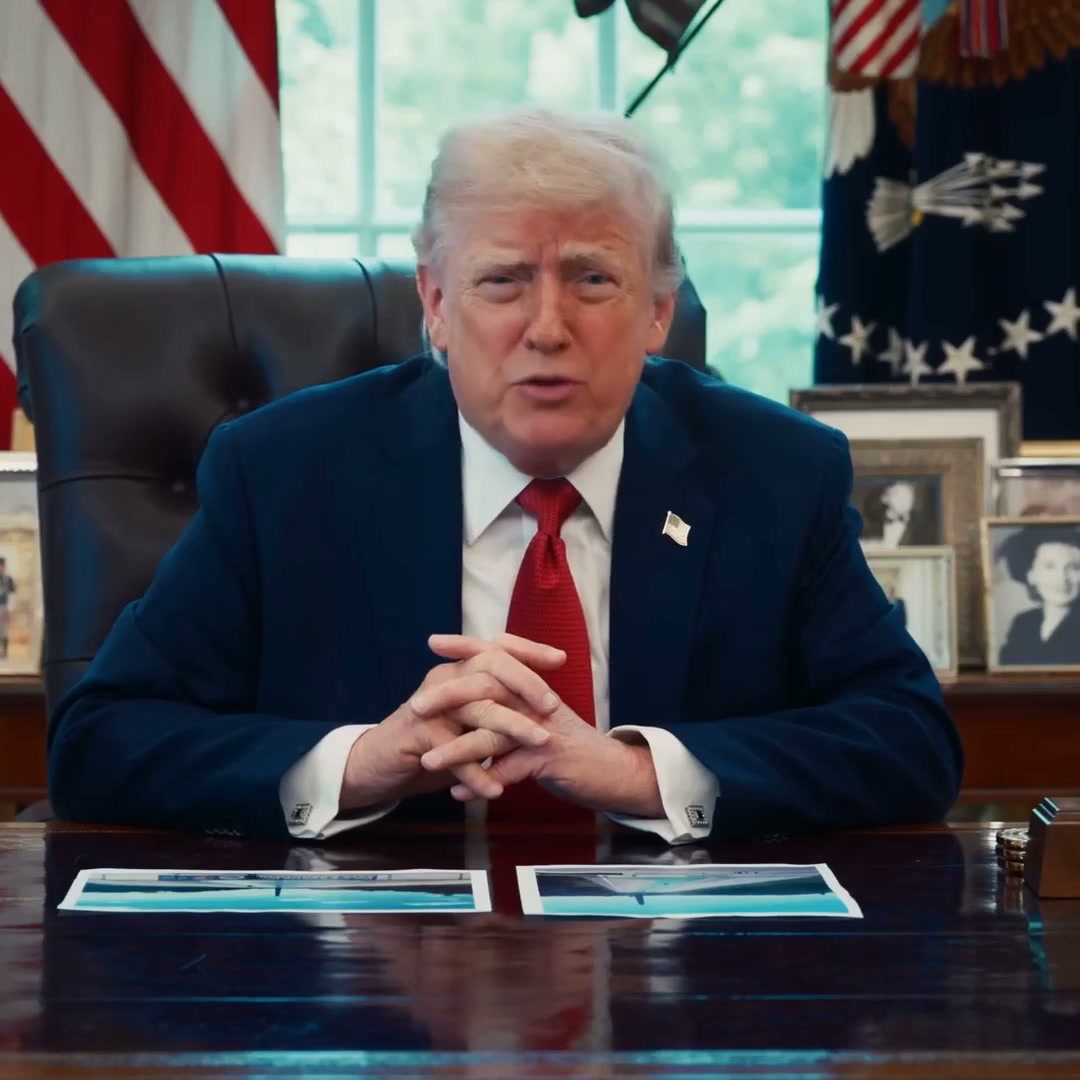 |
LatentSync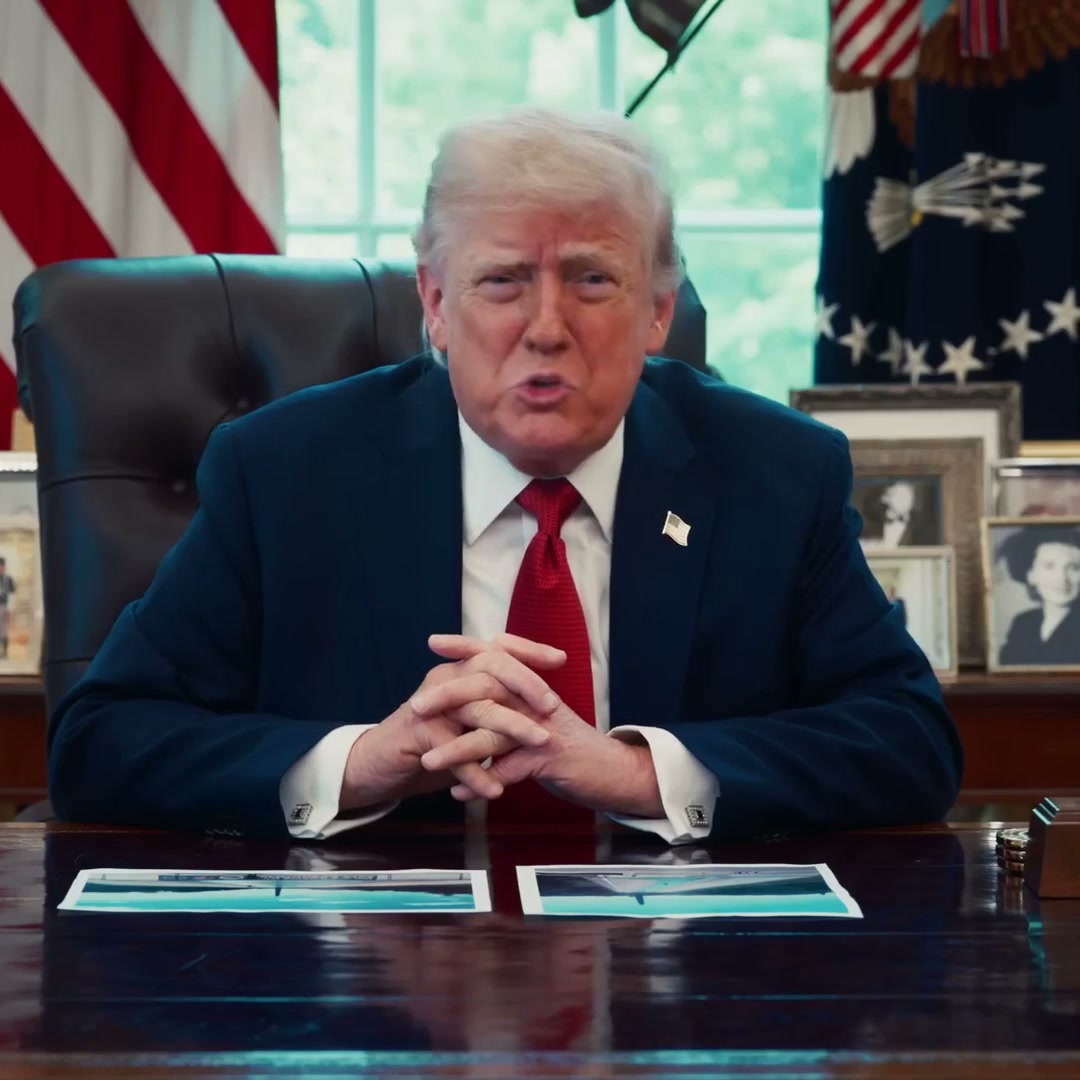 |
| Style-Talking RefGAN |
Wav2Lip |
MuseTalk |
LatentSync |
| Style-Talking RefGAN |
Wav2Lip |
MuseTalk |
LatentSync |
| Style-Talking RefGAN |
Wav2Lip |
MuseTalk |
LatentSync |
| Style-Talking RefGAN |
Wav2Lip |
MuseTalk |
LatentSync |
| Style-Talking RefGAN |
Wav2Lip |
MuseTalk |
LatentSync |
| Style-Talking RefGAN |
Wav2Lip |
MuseTalk |
LatentSync |
Style-Talking uses uv for environment and dependency management. The public inference path needs wav2vec/Audio2Motion dependencies and LivePortrait decoder dependencies.
uv sync --extra liveportraitThe inference pipeline also requires ffmpeg in the system PATH for audio extraction, frame sampling, and MP4 muxing.
ffmpeg -versionPlace the current inference models under the following paths. Checkpoints and model assets are intentionally ignored by git.
| Component | Required | Path |
|---|---|---|
| Audio2Motion checkpoint | yes | audio2motion_model_best.pt -> models/audio2motion/model_best.pt |
| wav2vec2 base 960h | yes | facebook/wav2vec2-base-960h -> models/wav2vec2/facebook_wav2vec2-base-960h |
| LivePortrait pretrained weights | yes | KlingTeam/LivePortrait -> models/liveportrait/pretrained_weights |
| LivePortrait face-process weights | yes | yolov8n-face.pt, 79999_iter.pth, resnet18-5c106cde.pth -> models/liveportrait/pretrained_weights/face_process |
| RefGAN renderer checkpoint | optional, recommended | renderer_refgan.pt -> models/renderer/renderer_refgan.pt; inference-only, keeps generator weights plus EMA and strips optimizers/discriminators |
The wav2vec model is facebook/wav2vec2-base-960h. The LivePortrait inference runtime source is bundled under src/style_talking/vendor/liveportrait_runtime; download the official LivePortrait weights from KlingTeam/LivePortrait and place them under models/liveportrait/pretrained_weights.
The expected local layout is:
style-talking/
├── models/
│   ├── audio2motion/
│   │   └── model_best.pt
│   ├── renderer/
│   │   └── renderer_refgan.pt      # optional
│   ├── wav2vec2/
│   │   └── facebook_wav2vec2-base-960h/
│   └── liveportrait/
│       └── pretrained_weights/
│           ├── liveportrait/
│           ├── insightface/
│           └── face_process/
│               ├── yolov8n-face.pt
│               ├── 79999_iter.pth
│               └── resnet18-5c106cde.pth
└── runs/
    └── inference/
Download or verify the required model assets:
uv run python scripts/download_checkpoints.py --group required --skip-existingDownload or verify the optional RefGAN renderer:
uv run python scripts/download_checkpoints.py --asset renderer_refgan --skip-existing
uv run python scripts/download_checkpoints.py --asset renderer_refgan --check-only
If the RefGAN checkpoint is not present, the original decoder path remains fully usable.
The preferred command takes a source video with audio and a target audio file, then writes the driven video directly to the requested MP4 path.
uv run python -m style_talking.cli.infer_video \
  --source-video examples/inputs/source_with_audio.mp4 \
  --target-audio examples/inputs/target_audio.wav \
  --output runs/inference/demo/result.mp4
Use the recommended RefGAN renderer after placing models/renderer/renderer_refgan.pt:
uv run python -m style_talking.cli.infer_video \
  --decoder refgan \
  --source-video examples/inputs/source_with_audio.mp4 \
  --target-audio examples/inputs/target_audio.wav \
  --output runs/inference/demo_refgan/result.mp4
Config files remain supported. The final video is written to the --output path; when --output is not provided, it is written as result.mp4 under the configured output_dir.
- Initial inference release: source-video/target-audio pipeline, style-prompted lip motion, original LivePortrait decoding, and final face blending.
- Optional RefGAN renderer release for reference-enhanced mouth details and public gallery videos.
- Technical report, model cards, released checkpoints, and reproducible inference examples.
- Full-face expression model and single-image driving.
Code is released under the MIT License. Citation metadata is available in CITATION.cff.